Designing Data-Intensive Applications
Ch. 1

Scalability

Scalability is not a single number — it is how a system copes with increased load. The right strategy depends entirely on what "load" means for your application.

Scalability describes how performance changes when load increases. A system that handles 10 users beautifully but collapses at 10,000 is not scalable. But "scalable" does not mean "infinitely fast" — it means you have a reasonable plan for growth.

Describing Load

Load is not just "number of users." For a social network, it might be posts per second and fan-out reads. For a search engine, it is queries per second and index size. Define the parameters that matter for your system and measure them.

Example: Twitter timelines

Twitter once reported ~300k requests/sec for home timelines and ~6k tweets/sec for writes. The read/write ratio and fan-out pattern (push vs pull model) dominated architectural choices.

Describing Performance

Throughput tells you how much work a system handles per unit time. Response time (latency) tells you how long an individual request waits. Both matter, but for interactive applications, tail latency — the slowest 1% or 5% of requests — often determines whether users perceive the system as fast.

Diagram

Approaches for Coping with Load

  • Vertical scaling: upgrade CPU, RAM, or disk on one machine. Simple but has hard limits.
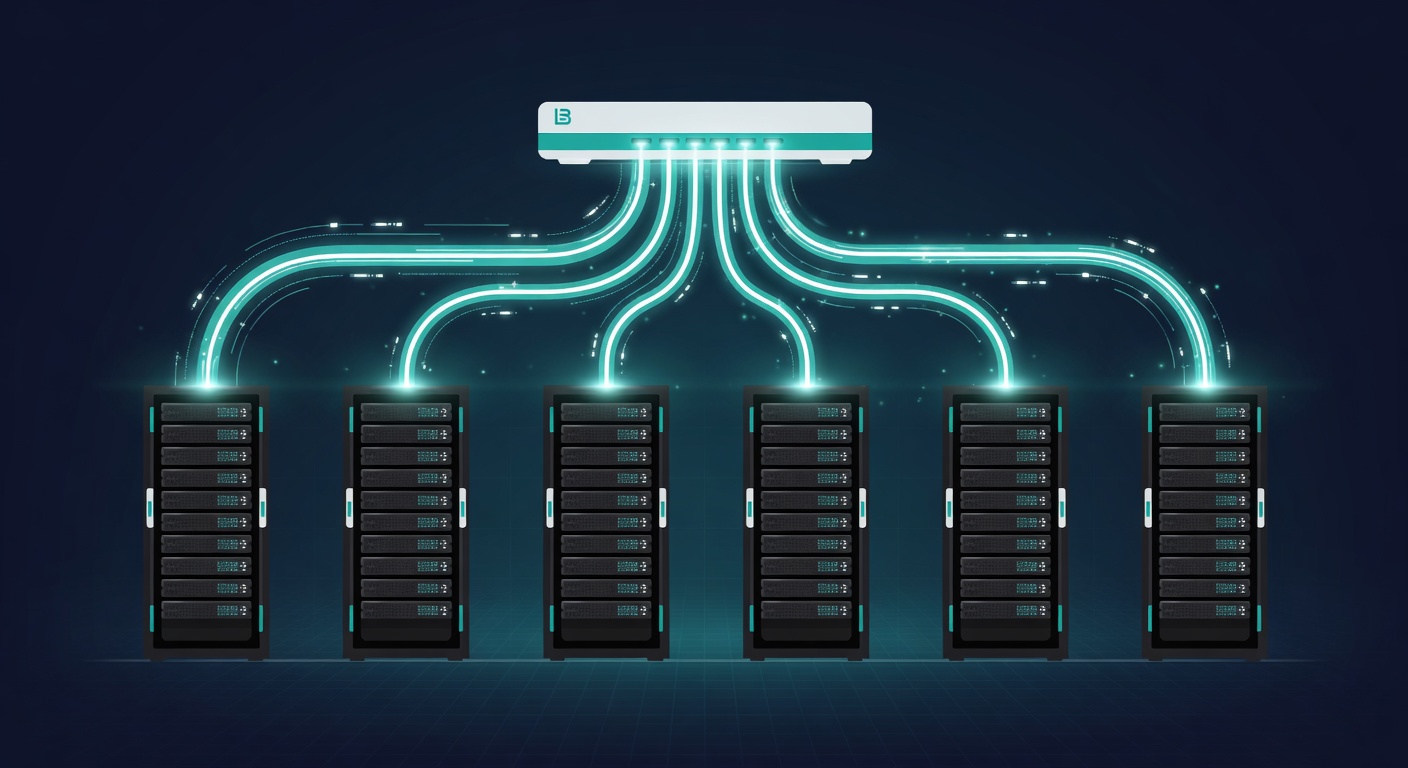
  • Horizontal scaling: distribute load across many machines. Requires partitioning and coordination.
  • Elastic scaling: automatically add/remove capacity. Great for variable load, harder to operate.
  • Tuning and optimization: sometimes a 10x improvement comes from a better algorithm, not more hardware.
In practice

Most web apps scale in layers: Cloudflare or AWS CloudFront caches static assets at the edge; Redis caches hot database rows (session data, product catalogs); PostgreSQL read replicas offload analytics queries; Kubernetes Horizontal Pod Autoscaler (HPA) adds pods when CPU or request rate spikes. Datadog or Prometheus tracks p95/p99 latency so you scale before users notice.

Facebook at scale

Meta's home timeline problem is pure scalability engineering: ~300k reads/sec vs ~6k writes/sec drove a hybrid fan-out strategy — precompute feeds for normal users (push), fetch on demand for celebrities with millions of followers (pull). Tail latency matters more than average load.

Diagram
typescript — Track p50/p99 latency — averages hide tail problems
const durations: number[] = [];

function percentile(p: number): number {
  const sorted = [...durations].sort((a, b) => a - b);
  const idx = Math.ceil((p / 100) * sorted.length) - 1;
  return sorted[Math.max(0, idx)];
}

// Google SRE: monitor p99, not just mean
console.log({ p50: percentile(50), p99: percentile(99) });
Conceptual illustration of traffic growing across distributed servers

Horizontal scaling spreads load, but introduces coordination challenges.

Key Takeaways
  • Load must be described with concrete parameters: requests/sec, read/write ratio, cache hit rate, etc.
  • Performance is measured in throughput (records/sec) or response time (latency percentiles).
  • Percentile metrics (p95, p99) matter more than averages for user experience.
  • Scaling can be vertical (bigger machine) or horizontal (more machines) — each has trade-offs.
  • Elastic systems automatically add resources under load; manual scaling is simpler but slower.
  • Redis caching, Cloudflare CDN, Kubernetes HPA, and PostgreSQL read replicas are common scaling layers.
throughputlatencypercentilehorizontal scalingvertical scalingRedisKubernetesCloudflarePostgreSQL